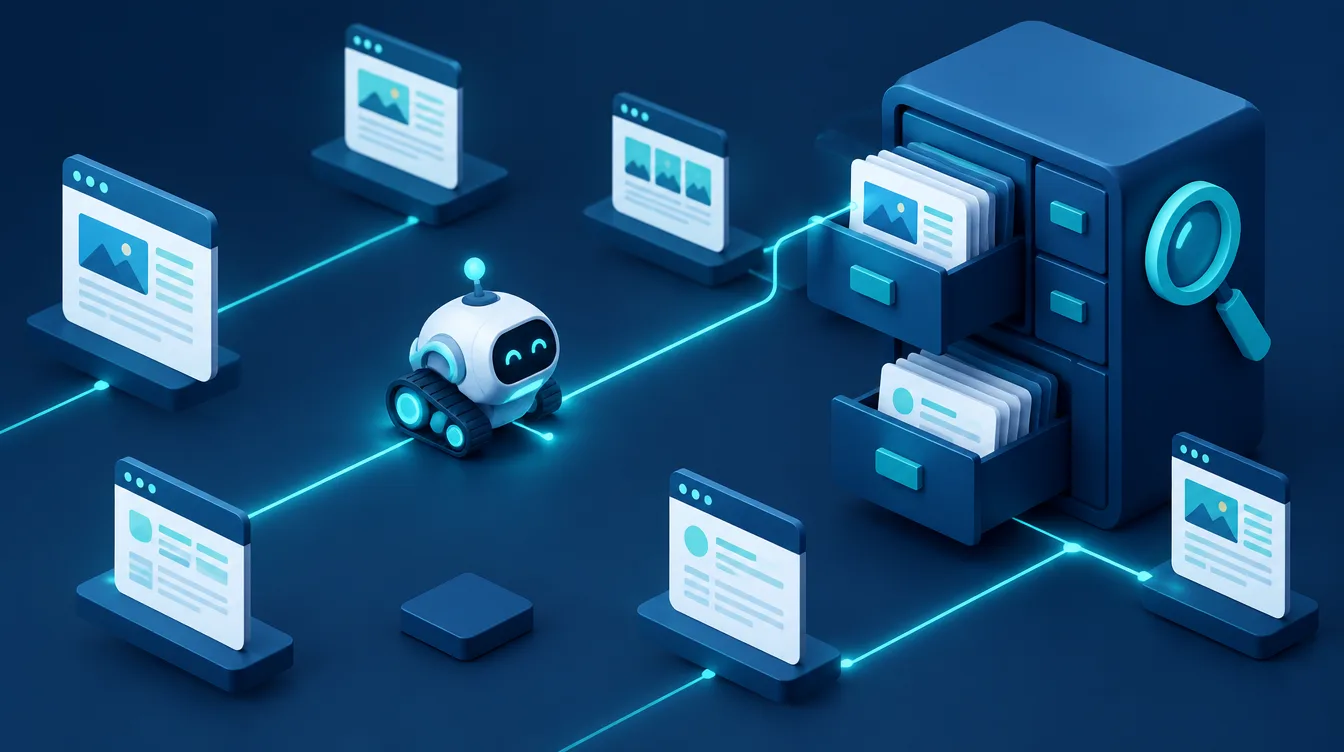
Google indexing means that Google has crawled a page, evaluated it and stored it in its index, the database it uses to build search results. A page that is not in the index will not appear for any query, however good the content is. Before a page can be indexed, a crawler (Googlebot, in Google's case) has to find and fetch it. This article explains how crawling and indexing work, how to find out why a page is missing from the index, and what actually helps.
In short:
- A search engine works in three stages: crawling (the crawler fetches the page), indexing (it stores the page) and serving results.
- Google's own documentation says it does not guarantee that every page will be crawled and indexed. 100% indexing is not the goal.
- The most common reasons pages are missing: a forgotten noindex, a robots.txt block, duplicates, thin content and pages with no internal links.
- You can check the status of a specific page with the URL Inspection tool in Google Search Console.
- A new page usually gets indexed within a few days, sometimes a few weeks. Repeated requests do not speed it up.
Crawlers, crawling and indexing: the three stages of search
A crawler (also called a robot, bot or spider) is a program that automatically downloads web pages and follows the links on them. Google uses Googlebot and Microsoft uses Bingbot; some regional search engines, such as Seznam in the Czech Republic, run their own. Crawling is the stage in which the crawler finds, fetches and processes a page. Indexing is the next step: the content is analysed and the page is stored in the index. Google describes the process like this:
| Stage | What happens | Typical problem |
|---|---|---|
| 1. Crawling | Googlebot finds the URL via links or a sitemap, fetches it and renders it, including JavaScript | server errors, robots.txt blocks, pages behind a login |
| 2. Indexing | Google analyses the text, title, alt text and images, picks a canonical version among similar pages and stores it | noindex tag, duplicate or low-value content |
| 3. Serving | when someone searches, Google picks the most relevant results from the index | the page is indexed but not relevant enough for the query |
An important distinction: being crawled does not mean being indexed. Google can crawl a page and decide not to store it. Conversely, a page blocked in robots.txt can still end up in the index without its content if other websites link to it.
How a crawler finds and crawls your website
There is no central registry of all web pages. Googlebot discovers new URLs in two main ways: through links from pages it already knows and through sitemap files. That is why a new page with no internal links that is missing from your XML sitemap is discovered slowly or not at all.
Google renders pages in a recent version of Chrome and runs JavaScript. If the main text or links only load after a click or another user interaction, the crawler may not see them.
How fast Google crawls depends on how quickly and reliably your server responds. According to Google's documentation, every site starts with the same conservative crawl capacity limit, which Google raises if there is demand for the content and the server stays healthy. Slow responses and 5xx or 429 errors slow crawling down. Fast, reliable hosting therefore affects indexing, not just website speed for visitors.
Crawl budget is mainly a concern for large sites, according to Google: roughly 1 million+ unique pages that change about weekly, or 10,000+ pages that change daily. For a typical business website or a smaller online shop, an up-to-date sitemap and a regular look at the page indexing report are enough.
How to check whether a page is indexed
- 1The site: operator – search Google for `site:yourdomain.com` for the whole site, or `site:` followed by the full page URL. It is a quick rough check; the result count is not precise.
- 2URL Inspection in Google Search Console – paste the URL into the search bar at the top. The tool shows whether the page is indexed, when Googlebot last crawled it, which canonical URL Google selected and, if it is not indexed, why. Test Live URL checks the current version of the page.
- 3The Page indexing report – an overview for the whole site: how many pages are indexed and why the others are not. Our Google Search Console guide covers setup and the other reports.
Why pages are not indexed: the most common reasons
The Page indexing report lists a specific reason for each URL that is not indexed. These are the ones we see most often on business websites:
| Reason in Search Console | What it means | What to do |
|---|---|---|
| Excluded by 'noindex' tag | the page tells search engines not to index it | if it should be in search, remove the noindex (often left over from a staging site) |
| Blocked by robots.txt | the crawler is not allowed to fetch the page | change the robots.txt rule if you want the page indexed |
| Crawled – currently not indexed | Google fetched the page but has not stored it yet | improve the content and internal links; Google says resubmitting is not needed |
| Discovered – currently not indexed | Google knows the URL but has not crawled it yet | add internal links, check server speed and the sitemap |
| Duplicate / Alternate page with proper canonical tag | Google chose a different URL as the main one | nothing, if the duplicates are intentional; otherwise consolidate content and canonical URLs |
| Not found (404) and Soft 404 | the page does not exist or only looks that way | redirect moved content with a 301 |
| Server error (5xx) and Redirect error | the server did not respond or the redirect chain is broken | fix with your developer or hosting provider |
Two points that are often confused. First, robots.txt blocks crawling, not indexing. If you want to keep a page out of search, use noindex and do not block the page in robots.txt; otherwise Google never sees the noindex rule. Second, 'Crawled – currently not indexed' is usually not a technical error but a sign that Google does not consider the content useful enough or distinct enough from other pages. Better writing following SEO copywriting principles, merging similar pages and more internal links all help.
How to get a page indexed by Google, step by step
For a new or updated page that should appear in search:
- 1Make sure the page has no noindex and is not blocked by robots.txt or a login.
- 2Check that it returns status code 200 and set the correct canonical URL (on an HTTPS site, only one version of each address).
- 3Add the page to your XML sitemap and submit the sitemap in Search Console. For updated pages, an accurate lastmod value helps.
- 4Link to the page from other pages on your site, ideally from the menu, a category or a closely related article.
- 5Click Request Indexing in the URL Inspection tool. There is a daily limit on requests, and a request does not guarantee indexing.
- 6Wait and monitor. Google suggests troubleshooting only about a week after submitting a sitemap or an indexing request.
How long indexing takes
According to Google's help pages, indexing a newly published page can take anything from a day or two to several weeks. Once you have fixed an issue in the Page indexing report, you can click Validate Fix; Google says validation typically takes up to about two weeks.
Why the time varies: it depends on how often Googlebot visits your site, how many internal links and backlinks point to the page, and how quickly your server responds. A new site with no links from other websites usually takes longer to get going than an established site that Googlebot visits daily.
What will not speed up indexing
- Repeated indexing requests for the same URL. The limit is daily and another request does not speed anything up.
- Google's Indexing API for ordinary pages. According to the documentation, it can only be used for job postings (JobPosting) and livestream video pages (BroadcastEvent).
- Paid 'fast indexing' services and bulk links from worthless websites. What helps in the long run is quality backlinks, which we cover in our article on link building.
- Generating hundreds of near-identical pages (for example, combinations of cities and services with almost the same text). Such pages typically end up as duplicates or not indexed.
Example scenario: a new website Google cannot see
This example is fictional but reflects situations we see in practice. A company launches a new website, yet three weeks later Google still does not show it even for the company name. URL Inspection reports 'Excluded by 'noindex' tag': the developer enabled the CMS option 'discourage search engines' on the staging site and forgot to turn it off at launch. After removing the noindex, submitting the sitemap and requesting indexing, the homepage and main service pages appear in the index within a few days, and the rest of the site follows as Googlebot works through the links. A website SEO audit catches mistakes like this, and they belong on every pre-launch checklist.
When to bring in an expert
You can usually fix a single missing page yourself with the steps above. It is worth bringing in an expert when the Page indexing report shows hundreds of non-indexed URLs, traffic dropped after a redesign or domain move, an online shop creates duplicates through filters and parameters, or the site relies on JavaScript and Google cannot see the content. Our SEO services include technical audits, indexing fixes and Search Console setup, and we also handle the technical side through website maintenance. If you have a specific problem, get in touch. More optimisation articles are in the SEO category.
Frequently asked questions
What is a crawler?
What is the difference between crawling and indexing?
How long does it take Google to index a page?
How do I check whether my page is indexed by Google?
Why did Google crawl my page but not index it?
Sources

Written by
Peter GáboríkProject Manager – AI, Automation & SEO
Project manager and founder of Weboptim. Builds growth strategies around SEO, automation and AI; in online marketing since 2017.
Related service
Tips that save time – once a month
One e-mail a month: a new guide, the automation of the month and one number from practice. No spam.